Abstract
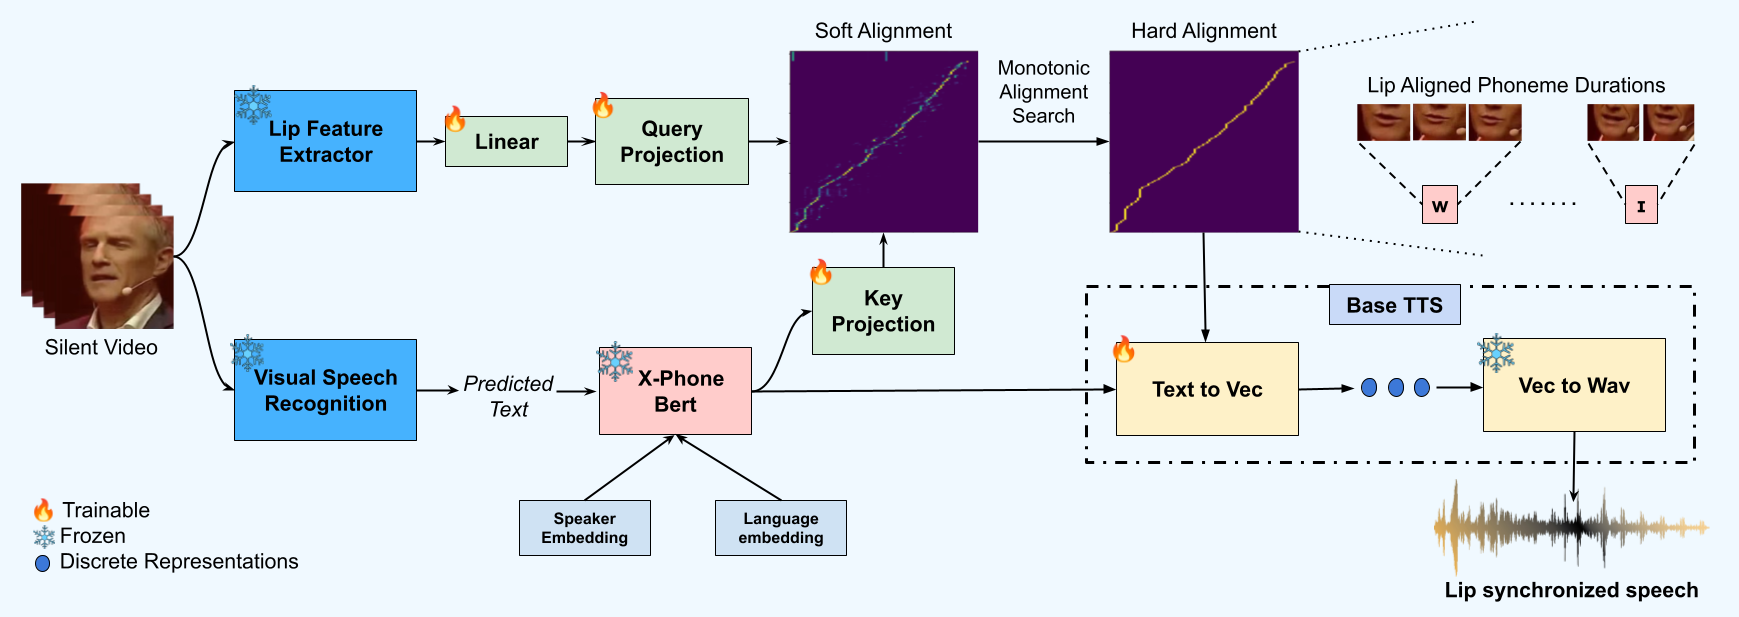
Lip-to-Speech synthesis aims to generate intelligible, natural-sounding, and temporally synchronized speech from silent visual recordings of a speaker. While recent end-to-end models have shown promising results, they require large amounts of training data and often lack out-of-dataset generalization. In this work, we introduce LipAdapter, a generic and efficient modular framework that adapts an existing frozen pre-trained Text-to-Speech model into a lip-synchronized speech generator. LipAdapter bridges the modularity gap between frozen Visual Speech Recognition(VSR) and Text-to-speech(TTS) models by aligning phoneme representation and lip embeddings via a novel text-to-video alignment module. Our model acheives state-of-the-art performance across multiple benchmarks in English while using 15× less training data than prior methods. We also demonstrate the model's zero-shot capabilities in multilingual lip-to-speech synthesis in French, German, Spanish and Portuguese.
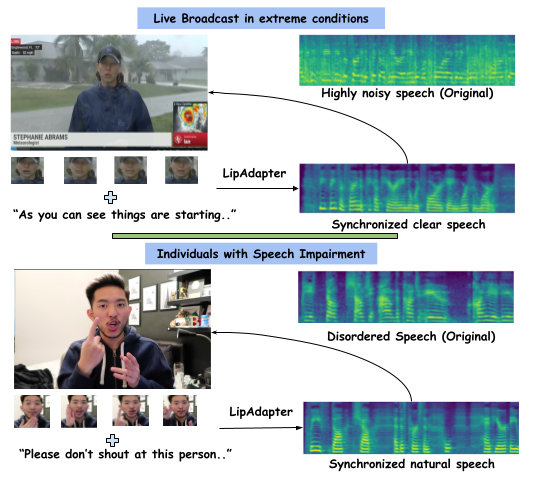
Applications in In-the-Wild Videos
Results in English
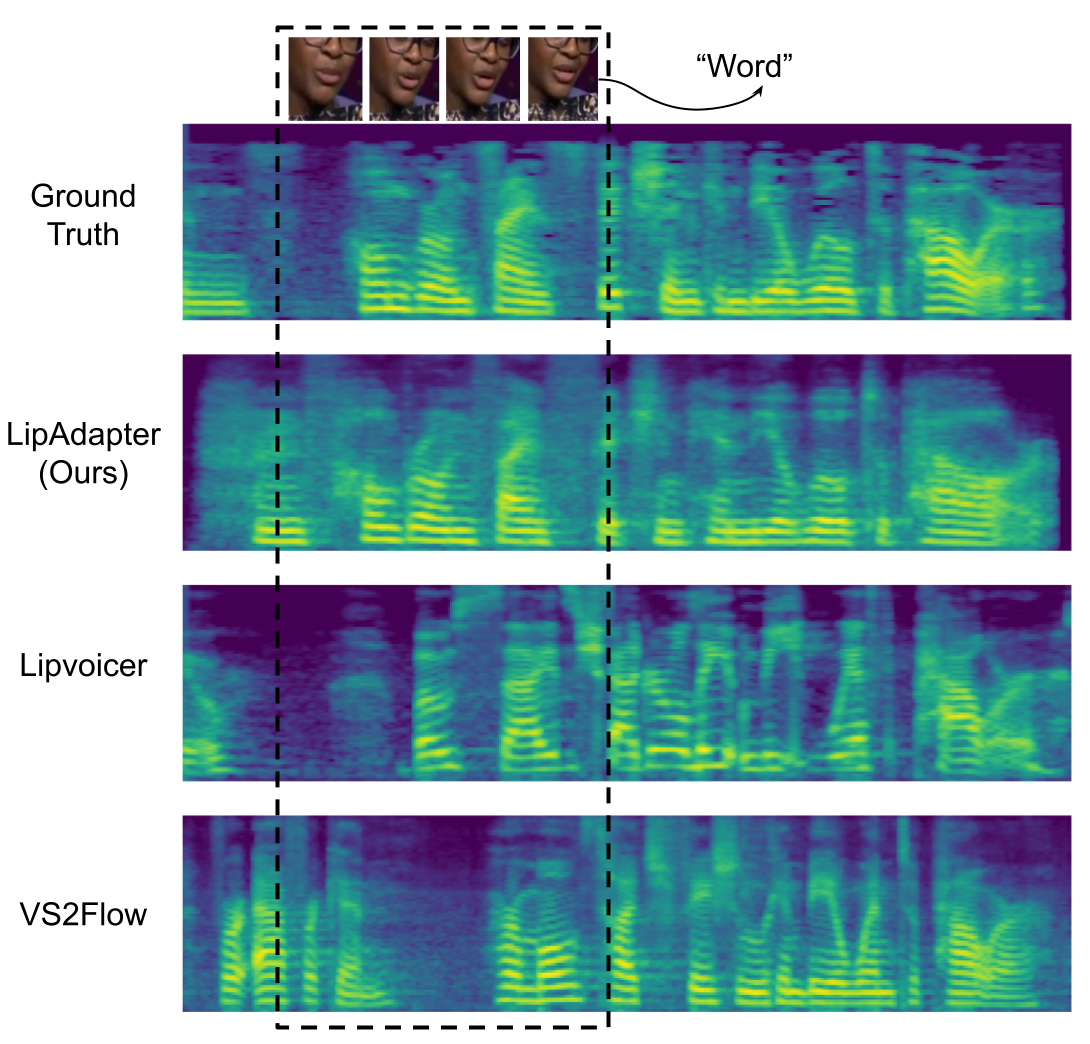
Error Analysis in LRS3 - Qualitative
Zero-Shot Multilingual Results
French
Spanish
German
Portuguese
Citation